
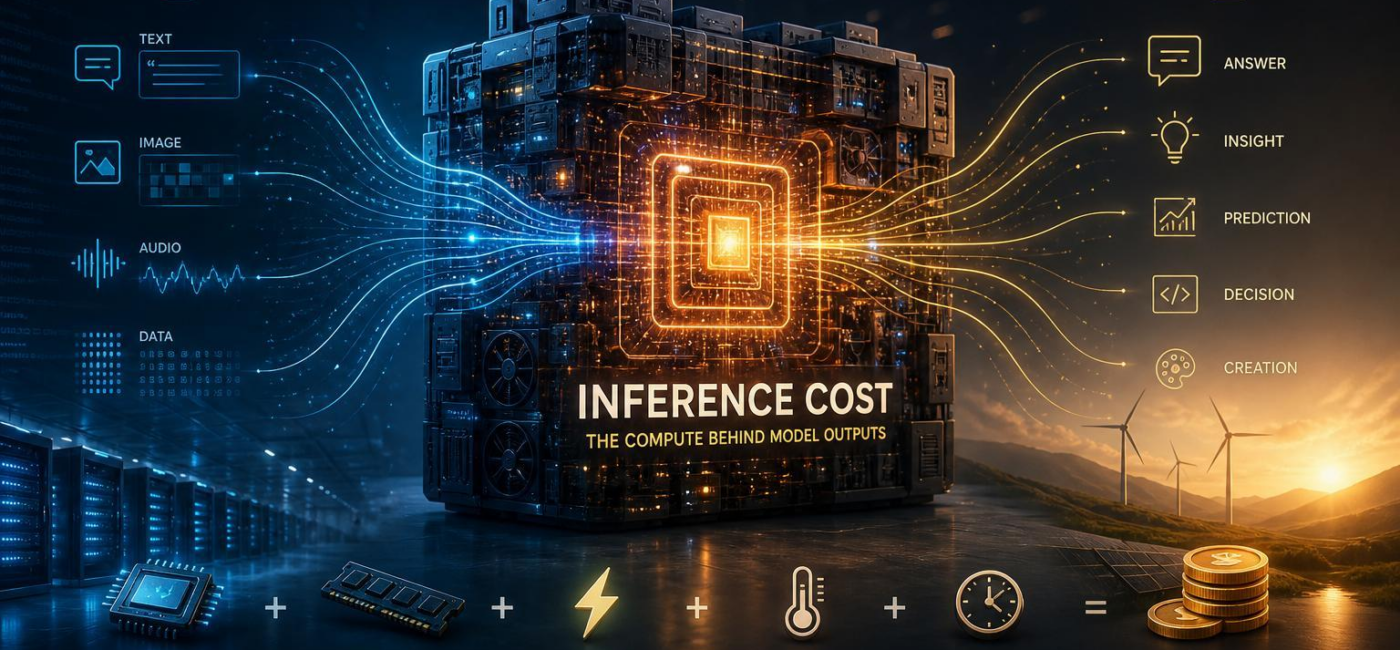
Inference cost is the compute expense of generating outputs from a trained model. In practical terms, it is the cost of turning a prompt into a useful response-whether that response is text, an image, audioor another kind of generated result.It is indeed easy too focus on a model’s headline price, but the real cost depends on how the model is used: how much context it receives, how long it responds, how many requests arrive at onceand how efficiently the system serves them.
Understanding what drives inference cost
Every generated token requires work. The model processes the input, moves through its layersand uses accelerator compute and memory to produce the next token. Larger models generally require more work per token, but model size is only one part of the equation.
Input length matters because the system must process the context before it can answer. Output length matters because each additional token adds another generation step. A short prompt with a long response can still be expensive, while a lengthy document can raise costs before the model generates a single word. Traffic volume adds another variable: a workload that is inexpensive for one request can become costly when thousands of requests arrive at the same time.
Memory use also plays a major role. During generation, serving systems commonly retain details from earlier tokens in a cache so the model can continue the response without recalculating everything from scratch.As prompts and conversations grow,that cache consumes more accelerator memory and can reduce the number of requests the system can handle at once. Providers may address this through batching, routing, model variants, quantizationand cache management, but each choice involves a trade-off between latency, throughputand quality.
The key point is that inference cost is not a flat fee per request. It reflects the compute and memory required for a particular prompt, model, and response.
Measuring cost alongside speed
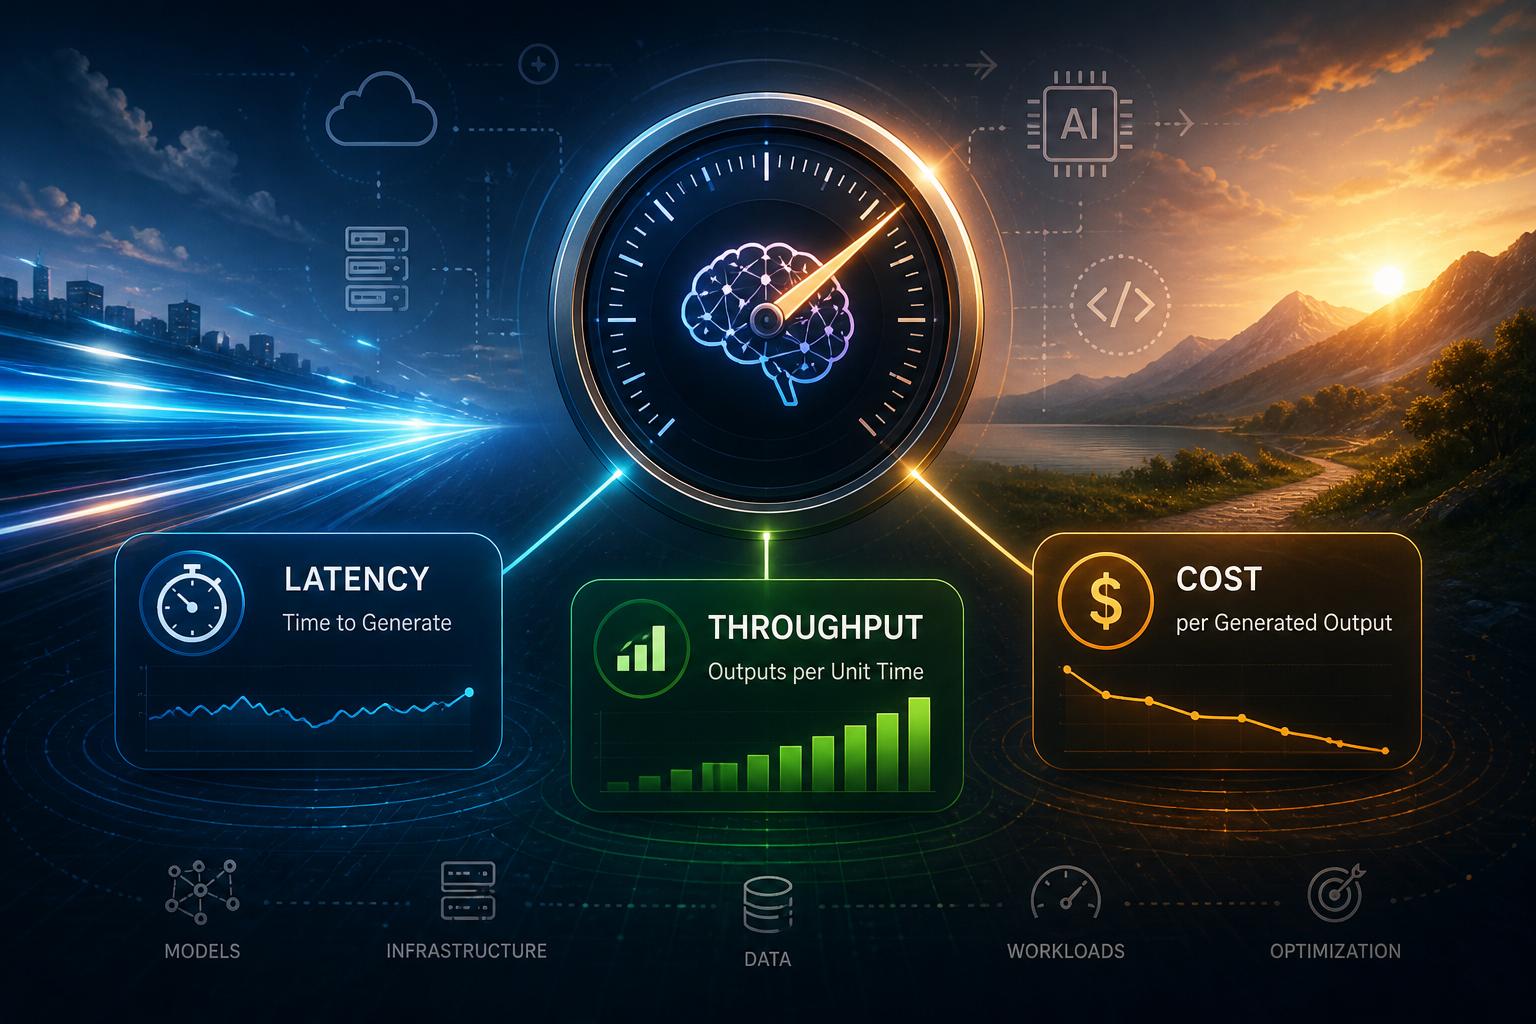
Inference spending becomes meaningful when it is tied to what users actually receive: a completed answer, a generated image, a second of synthesized audioor another defined unit of output. Latency measures the wait, throughput measures capacityand cost per useful output shows what the work is really costing.
These measures need to be read together. A service may appear inexpensive on a per-token basis but become costly when prompts are consistently oversized, generated outputs are discardedor retries are frequent. In the same way, a model can respond quickly to one person yet perform poorly when concurrent requests begin to queue.
It helps to separate time to frist token from total completion time. The first tells you how quickly a user sees the response begin; the second tells you how long they wait for a usable result. throughput shoudl be measured during realistic busy periods, not just in isolated tests. Cost should include input processing, generated output, retriesand the infrastructure needed to serve the request.
Rather than relying on a single headline price, compare representative requests. for a customer support assistant, that might be one customer question and an accepted reply. For document processing, it might be a page summarized to a specified length. Keep that definition consistent, then observe how cost and performance change with prompt size, output length, concurrencyand model choice. This frequently enough reveals trade-offs that are easy to overlook: a shorter answer may reduce both cost and wait time, while a somewhat more expensive model may lower the cost of a useful result by reducing revisions and retries.
| Measure | Useful question | What it can reveal |
|---|---|---|
| Time to first token | How soon does the response begin? | Perceived responsiveness |
| Completion time | How long until the result is usable? | End-to-end waiting time |
| Outputs per hour | How much demand can the service handle? | Capacity under real load |
| Cost per accepted output | What does a useful result actually cost? | Waste from retries and revisions |
Making model serving more efficient
Not every request needs to be handled in isolation. Batching groups compatible requests so an accelerator can process more work at once. That can improve throughput and reduce the cost per generated token, tho ther is a practical limit: waiting too long to form a batch can make an interactive product feel sluggish.
For that reason, many serving systems balance small, dynamic batches against response-time expectations.Interactive traffic may need to move quickly, while background work can frequently enough tolerate a short queue. Caching can also reduce unnecessary compute. Reusing common responses, retrieved context, embeddingsor previously processed prompt prefixes may avoid repeating work when requests share the same instructions or content.
| Serving choice | Cost effect | Main caution |
|---|---|---|
| Dynamic batching | More output per accelerator cycle | Can add queue time |
| Prefix and response caching | Avoids duplicate model work | Requires careful cache freshness |
| Hardware matching | Reduces wasted capacity | Must fit model and traffic pattern |
Hardware should match the workload rather than follow a default preference for the largest available accelerator. A modest model with limited traffic may be less expensive to run on smaller or shared capacity. Sustained, high-volume generation may justify hardware with greater memory bandwidth and more parallel compute.
Memory deserves the same attention as raw processing power. Model weights, active requestsand the cached state used during generation all compete for available memory. Reliability matters, too. A cheaper machine is not necessarily the economical choice if it causes frequent cold starts, requires awkward model sharding, or leaves expensive capacity sitting idle. The goal is straightforward: keep hardware doing useful inference work without making users wait longer than they are willing to wait.
Keeping costs under control
Inference costs become more predictable when they are treated as an operating constraint instead of a surprise at the end of the month. The main levers are familiar: model choice, token volume, output length, request frequencyand peak concurrency.Smaller or specialized models may be a sensible fit for classification, routing, extractionand routine support tasks. More capable models can then be reserved for work that truly needs them.
Cost controls should not come at the expense of reliability. A hard limit that simply rejects useful requests can create a worse experience than a thoughtful fallback.It is often better to define when a request can use a lower-cost model, when cached material is appropriateand when a task should be escalated to a more expensive option.
Teams should also look for quite sources of waste: oversized system prompts, unnecessary conversation history, output limits that are far longer than users needand automated retries that multiply failed calls. Per-feature and per-user spending limits can make these patterns easier to spot before they become a larger problem.
managing inference cost is less about finding one perfect model or one perfect piece of hardware. It is indeed about matching the amount of compute to the value of the task, measuring the results users actually acceptand revisiting those choices as traffic and product needs change.
AI tools built by Emerald Force
Built and supported by Emerald Force.
You might also like
- Few-Shot Prompting: Learning from a Few Examples
- Inference Cost: The Compute Behind Model Outputs
- How to Benchmark Tools Before Buying: A Practical Guide
- Can AI Remove Backgrounds? A Proven Vision Use Case
- How AI Clusters Customer Feedback and Detects Sentiment
- AI Center of Excellence: Standards and Adoption
- Where AI Coding Excels: Tests, Refactors, Scaffolds
- AI Can Fake Documents-Why Verification Is Essential
- Can AI Identify You From a Photo? Key Risks
AI Models Explained: From Inputs to Outputs